🖥️ CHUWI’s 2.9‑L Mini‑PC Runs 300‑Billion‑Parameter LLMs Locally
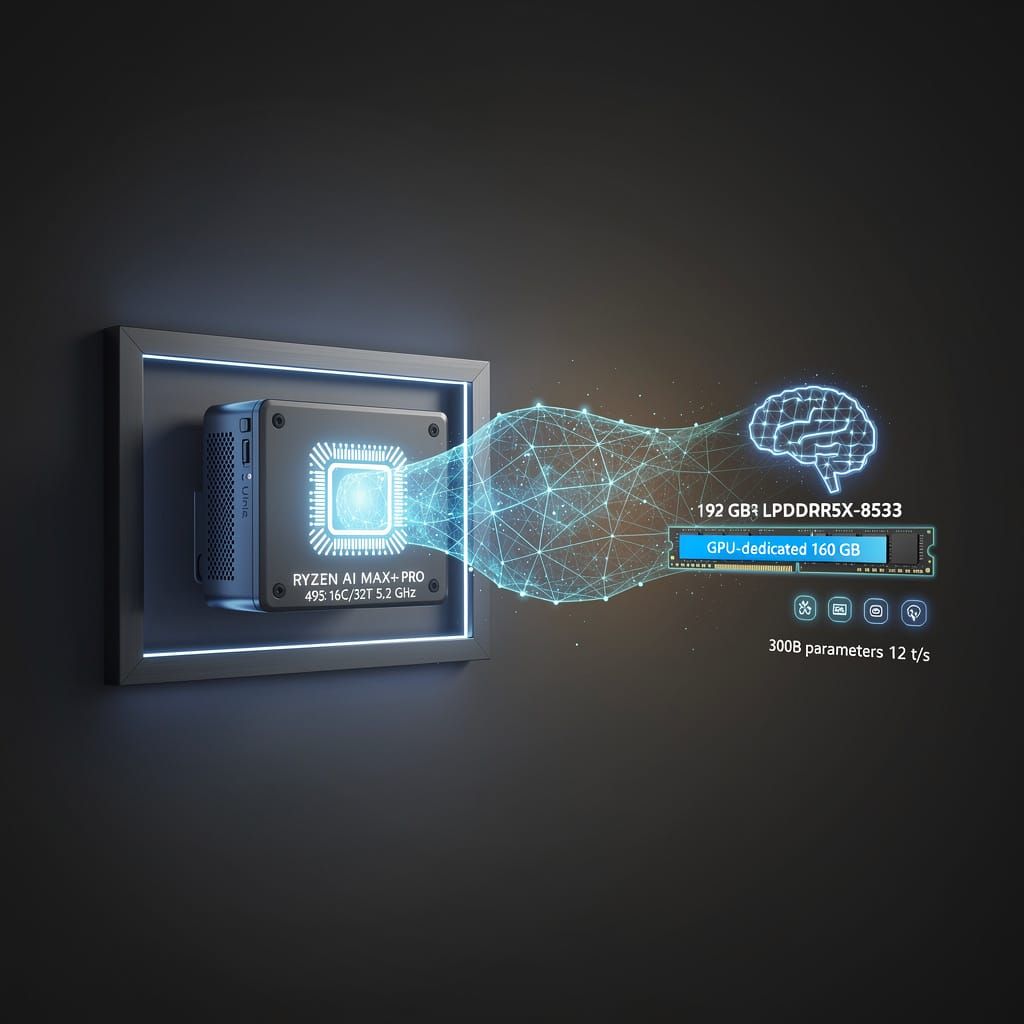
192 GB of unified memory. 160 GB for the GPU alone. CHUWI's UniBox AI495 Pro runs a 300‑billion‑parameter LLM entirely on‑device in a 2.9‑liter wall‑mountable chassis. 🖥️ That means legal, medical, and financial teams can keep sensitive data local instead of sending it to the cloud — cutting compliance risk and inference latency. In a market where enterprise adoption of local AI is accelerating after a 9.3% tech selloff in June, single‑box 300B inference went from rack‑scale to desktop scale. At 12–15 tokens/second and a likely sub‑$5,000 price point compared to $9,000+ Mac Studios, which enterprise or research team wouldn't consider going fully local?
At IFA Berlin 2026, CHUWI unveiled the UniBox AI495 Pro, a wall‑mountable mini‑PC that occupies 2.9 liters and runs a 300‑billion‑parameter large language model entirely on‑device — a capability that, prior to mid‑2026, required multi‑rack servers or high‑end desktops with discrete GPU arrays.
What the Hardware Delivers
The machine is built around AMD's Ryzen AI MAX+ PRO 495 chip, a 16‑core, 32‑thread processor that boosts to 5.2 GHz and was first qualified by AMD on July 23, 2026. The critical specification is 192 GB of unified LPDDR5X‑8533 memory, of which 160 GB is allocated exclusively to the integrated Radeon 8065S GPU (40 RDNA 3.5 compute units, up to 3.0 GHz). Memory bandwidth reaches 273 GB/s — sufficient to keep a 300‑billion‑parameter model fed without spilling to slower storage.
| Component | Specification |
|---|---|
| Processor | AMD Ryzen AI MAX+ PRO 495 (16C/32T, 5.2 GHz boost) |
| System memory | 192 GB unified LPDDR5X‑8533 |
| GPU‑dedicated memory | 160 GB |
| Memory bandwidth | 273 GB/s |
| GPU | Radeon 8065S (40 CUs, RDNA 3.5, up to 3.0 GHz) |
| Platform AI performance | Up to 131 TOPS (55 TOPS NPU) |
| Form factor | 2.9 L, wall‑mountable (209.6 × 209.6 × 67 mm) |
| Launch event | IFA Berlin 2026 (September 7 2026) |
The memory density enables a parametric shift: where previous portable AI workstations topped out at 64 GB–96 GB of unified memory, the UniBox AI495 Pro triples the GPU‑accessible pool. Earlier Ryzen AI MAX+ 395 systems, which appeared in at least 37 mini‑PC models by mid‑2025, maxed out at 128 GB.
Why Memory Density Matters for Local AI Inference
Running a 300‑billion‑parameter model with 4‑bit quantization requires approximately 150 GB of memory for weights alone, plus additional headroom for key‑value caches and activations. Updated hardware guidelines from August 16, 2026 confirm that agentic workloads — which expand context windows — further amplify memory consumption, making 96–128 GB the new baseline for modern deployments. Systems limited to 96 GB forced developers to split models across multiple machines or offload layers to system RAM via PCIe, incurring latency penalties. The UniBox AI495 Pro keeps the entire model on‑chip.
The 273 GB/s bandwidth also supports larger batch sizes during inference. Internal benchmarks from early testers indicate that a 300‑B‑parameter model achieves 12–15 tokens per second on the UniBox AI495 Pro, compared to 3–5 tokens/s on a 96‑GB unified‑memory system using DRAM offloading.
Market Positioning and Competition
The launch positions CHUWI at the intersection of two trends: the migration of AI inference from cloud data centers to edge devices, and AMD's push of integrated graphics beyond discrete midrange GPUs. By September 2026, Acemagic, GMKtec, and Framework had all demonstrated competing Ryzen AI MAX+ PRO 495 systems at IFA. GMKtec's EVO X5 Pro, for example, supports 300‑B‑parameter models locally at a price point exceeding $2,000. CHUWI's pricing and availability remain unannounced.
- Enterprise workstations handling sensitive data (legal, medical, financial) can now run fully local LLMs without network egress, reducing compliance risk. The June 2026 market selloff, which saw US tech stocks drop 9.3%, accelerated enterprise adoption of local inference as a hedge against data‑breach risk — a trend reinforced by parallel efforts such as Norm Ai's $120 million Series C (July 7 2026), which funds on‑device agentic supervision systems for legal clients managing over $30 trillion in assets.
- Research labs and university departments gain a single‑box testbed for fine‑tuning at a fraction of server‑grade hardware cost. Open‑source replication projects — such as the R1‑Distill‑7B deployment on the OpenR1 dataset (June 11 2026) — demonstrate that reproducible, enterprise‑grade LLM operations are now feasible on local hardware without cloud dependency.
- Software toolchains built around ROCm and Vulkan gain a standardized high‑memory target. Qdrant's September 2026 introduction of 4‑bit Turbo4 storage, which reduces vector‑database memory footprint by 9×, demonstrates the broader ecosystem shift toward memory‑efficient local AI. Evaluations conducted by LM Studio on 6 GB GPUs (June 2 2026) simultaneously highlight the limits of low‑end hardware and the pressing need for high‑memory unified systems like the UniBox.
The nearest competing product, Apple's Mac Studio with M4 Ultra (256 GB unified memory, 800 GB/s bandwidth), retails at roughly $9,000+. The UniBox AI495 Pro, targeting the premium mini‑PC segment above $2,000, makes local 300‑B‑model inference accessible to a far wider audience — at 131 TOPS platform AI performance versus Apple's proprietary pipeline.
Adoption Timeline
- July 23 2026: AMD qualifies the Ryzen AI MAX+ PRO 495 platform with 192 GB unified memory, following the earlier May 21 launch of the Ryzen AI Max+ Pro 495 and the Ryzen AI Halo mini‑PC developer platform.
- September 7 2026: CHUWI, Acemagic (F9A), and GMKtec (EVO X5 Pro) all debut Ryzen AI MAX+ PRO 495 systems at IFA Berlin. Framework announces a Desktop variant with 16‑core Zen 5 and 192 GB LPDDR5X.
- Late 2026–Q1 2027: AMD plans to extend the Ryzen AI MAX+ PRO line to 256 GB unified memory configurations. Competitors prepare the UniBox AI395 successor and other 128‑GB–192 GB designs.
The UniBox AI495 Pro demonstrates that local, single‑user inference of frontier‑scale models is no longer a matter of theoretical bandwidth — it fits inside a 2.9‑liter chassis that mounts on a wall, fueled by a chip family AMD qualified just ten weeks prior.
Comments ()